Search This Blog

Showing posts with label programming. Show all posts

Wednesday, August 04, 2010

NWScript Stack System

Note: SW has written a new post, talking about NWScript in general, akin to my post yesterday (though possibly in more detail than mine; I haven't actually read it all yet).

So, now we know where we are (the NWScript system), and where we need to go (LLVM assembly). Now, how do we get there?

Well, a lot of things are simple enough, requiring only trivial use of LLVM and a parser. But after investigating the NWScript system for this purpose, I identified several areas that would be nontrivial and would require some thought and effort, which I'll discuss.

The first challenge - that is, a nontrivial design issue - was the stack machine. Stack machines are easy to interpret, but harder to convert to something like LLVM assembly that uses registers (like real assembly languages) and strongly declared and typed variables (unlike real assembly languages). Stack machines use a huge number of stack locations during execution, the vast majority of them (more than 96% of them, in one sample I looked at) temporary copies that last only until the next math (or other) instruction. From the opposite perspective, it's necessary that all accesses of a single variable be mapped to the same memory location, regardless of where the variable is, relative to the top of the stack. It's even possible that multiple separate locations in the code could create a stack location that represents only a single variable, despite being created in multiple places.

To illustrate these problems, a few examples:

// var1 * 0x1E
CPTOPSP FFFFFFEC, 0004
CONSTI 0000001E
MULII
// + var2
CPTOPSP FFFFFFEC, 0004
ADDII
// var3 =
CPDOWNSP FFFFFFF0, 0004
MOVSP FFFFFFFC


Here, we can see two stack locations are created that do not represent variables at all, but rather temporary parameters to the MUL instruction. A third temporary that also is not a real variable is created as the return value to the MUL instruction, which is then used as a parameter to the ADD instruction along with a fourth temporary copied from a variable. Finally, a fifth temporary is created for the return value from the ADD instruction, which is copied down to a result variable and destroyed. The C code for this would be var3 = (var1 * 0x1E) + var2;

// if (3 == 0)
00000045 CONSTI 00000003
0000004B CONSTI 00000000
00000051 EQUALII
00000053 JZ off_00000065
// true: var = 1
00000059 CONSTI 00000001
0000005F JMP off_0000006B
// false: var = 2
00000065 CONSTI 00000002
0000006B

In this second case, we have an optimized variable initialization where a stack location is created in two separate locations (depending on whether a condition is true), but is in reality only a single variable. This is from a script that has int g_i = (3 == 0 ? 1 : 2);

It may also be possible to use the stack as, well, a stack, building up a variable-length list of things as they're processed in one loop, then popping them in a second loop. I can't think of a practical use for this off the top of my head (something that is both useful and couldn't be accomplished any other way), but it might be possible.

So, the stack system poses challenges related to identifying variables. However, a second, less obvious problem exists, although it's not as specific to stack machines. In this case, the problem relates to functions. In NWScript, a call consists of:
  1. Reserve a temporary slot on the stack for the return value
  2. Push the parameters in reverse order
  3. Call the function
  4. Copy and pop the return value
As implied, the caller allocates space for the return value, and the called function must remove all parameters before return. This causes a problem for us, because we need to keep track of stack positions so that we can locate variables, and alignment of the stack would be impossible as long as we have no idea what a function call will do to the stack.

The solution I came up with to this problem (as well as other problems, which I'll talk about in the future), was a two-pass system that performs analysis and intermediate code generation (intermediate code is an expanded form which deals with variable references rather than the stack, making it much easier to work with; this intermediate code would then be converted to the output code type in a third pass). The two passes could have been done in a single pass, but this would have been quite messy and needlessly memory-hungry, as opposed to the more elegant and efficient two-pass system.

First Pass
The first pass through the script file performs a couple tasks. It identifies functions and code flow blocks: the largest groups of instructions that execute as an atomic unit and have only a single execution path from the first to the last instruction in the block. It also determines the number of parameters and return values for each function (in NWScript, functions only have a single return value, but when the bytecode is generated, structs and other complex types are flattened to primitive types, making it look like there are multiple return values).

This pass is quite simple. It proceeds by scanning through the code, beginning with the main function, parsing each instruction as it goes. The current stack pointer (but not an actual stack) is maintained from instruction to instruction. As well, a code flow graph is created by watching for branch instructions and creating new flow blocks and splitting old ones (if a branch jumps into the middle of an existing flow, that flow must be split, as it's not an atomic unit). Finally, entries for functions are created as they're encountered.

The biggest trick here is dealing with function calls. The effect of other operations on the stack can be trivially calculated by decoding the instruction, but we can't step past a call instruction until we know the stack displacement. The same is true for calls to API functions, but we already know exactly what they do to the stack, as those are a closed set.

What I decided to do was to use a task queue. When a new, previously unencountered function is encountered in a call, a new function entry and task queue entry corresponding to the function are created, and the current analysis task is marked as blocking on that function. Conditional branches are handled more or less the same way: a new task is created for one branch, though not blocking on anything, and analysis continues at the other branch. Whenever the current task blocks (e.g. it calls an unanalyzed function), analysis switches to the first task in the queue that is not blocking on anything, and execution continues from there.

Tasks ultimately complete when a return is encountered. When that occurs, the number of parameters for the function is calculated by the difference in stack pointer from the beginning of the function to the end. The function is marked as analyzed, and any tasks blocking on the function are unblocked and may potentially continue analysis. The number of return values is determined by observing the lowest stack address written to within the function. This requires that all paths through a function be evaluated, but as the return value does not affect overall stack displacement, tasks blocking on the function may resume prior to determining the exact number of return values.

While this can potentially generate a large number of blocked tasks in the queue, so long as the script does not contain a loop that has no exit path or a function that calls itself recursively without a path that returns, this is guaranteed to ultimately locate a function that can return. While functions may have multiple paths from beginning to end, and all must eventually be traversed, we need only a single path to return to know the function's displacement, resulting in unblocking of tasks waiting on that function. This discovery process cascades, and analysis of all routes through the script eventually completes.

Second Pass

After the completion of the first pass, we now know all functions, code flows, and the number of parameters and return values for each function. The second pass performs several functions:
  • Determine the types and locations of local and global variables and create variable objects for them
  • Determine the types of function parameters and return values
  • Generate the intermediate code
The second pass is somewhat simpler in code flow logic, but much more complicated in terms of the amount of work done. It too operates on a task queue system, but has no concept of blocking - the task queue exists merely to queue up alternate paths for processing after the current path completes. It operates locally on a function using the code flow graphs as rails to guide analysis, processing each function completely before moving on to the next.

The code for this pass resembles a mini-interpreter (well, I suppose it is), including a stack filled with references to the variable objects at that location. A new variable object is created each time some manner of instruction pushes a variable on the stack. To make things simpler during processing and final code generation, variables are explicitly created and destroyed with dedicated instructions in the intermediate code, unlike the implicit generation/destruction in the bytecode.

Because the stack is necessary to determine what variables individual instructions reference, functions must, as in the first pass, be executed in control flow order, rather than simply evaluating each flow in the list in random order (as we do with functions). The stack at the end of each flow is saved until analysis of the function completes, so that successor flows evaluated later can pick up the stack where the previous flow left off (and one other reason I'll explain in a second).

Most of the details of the second phase relate not to the topic of this post, but to later ones. One detail worth mentioning, however, is that after all flows for a function have been evaluated, stack merging occurs. Because it's possible that a stack location might be created in two separate locations that together form a single variable (as in the example above), when multiple flows converge in a single successor flow, the stacks from each of the predecessor flows must be merged: for each offset in the stacks, the variables in each corresponding position are merged, eliminating all but one copy. Because the intermediate code representation is flexible, variable merging is trivial, and requires no modification of the intermediate code itself.

However, for this and other reasons, this compiler does not, as of now, support variable use of the stack: when the stack is extended to a variable length by a loop or some such, as mentioned earlier. There is no way to generate such a structure in NWScript (the scripting language), and manually-written bytecode files are anywhere between incredibly rare and non-existent, so we thought that was a reasonable omission.

One really cool thing about this system, however, is that the host program can be a hybrid of interpretation and compilation. E.g. the compilation of all scripts can be offloaded to a worker thread when a module is loaded to compile in the background, and the host program can use the interpreter for a script until compilation of that script finishes. The interpreter could also be used as a fall-back for scripts the compiler is unable to compile for one reason or another, such as those with evil stack usage.

Below is an example of a random block (a flow, to be precise) of bytecode and its corresponding intermediate code. Note that the addresses differ by 0xD because the bytecode block is generated by a disassembler that includes the file header in the address:

00005282 ACTION GetTimeHour(0010), 00
00005287 CPTOPSP FFFFFF34, 0004
0000528F ACTION StringToInt(00E8), 01
00005294 ACTION GetTimeHour(0010), 00
00005299 SUBII
0000529B ADDII
0000529D CPDOWNSP FFFFFF00, 0004
000052A5 MOVSP FFFFFFFC
000052AB CONSTI 00000000
000052B1 CONSTI 00000000
000052B7 CONSTI 00000000
000052BD CPTOPSP FFFFFEF8, 0004
000052C5 ACTION SetTime(000C), 04
000052CA CPTOPSP FFFFFF04, 0004
000052D2 CONSTI 00000000
000052D8 LTII
000052DA JZ off_00005304


00005275: CREATE 01F36000 ( temp SSA int )
00005275: ACTION 0010 (0) 01F36000 ( temp SSA int )
0000527A: CREATE 01F36030 ( temp SSA string )
0000527A: ASSIGN 01F36030 ( temp SSA string ), 02102C10 ( string )
00005282: CREATE 01F36060 ( temp SSA int )
00005282: ACTION 00E8 (1) 01F36060 ( temp SSA int ), 01F36030 ( temp SSA string )
00005282: DELETE 01F36030 ( temp SSA string )
00005287: CREATE 01F36090 ( temp SSA int )
00005287: ACTION 0010 (0) 01F36090 ( temp SSA int )
0000528C: CREATE 01F360C0 ( temp SSA int )
0000528C: SUB 01F360C0 ( temp SSA int ), 01F36060 ( temp SSA int ), 01F36090 ( temp SSA int )
0000528C: DELETE 01F36090 ( temp SSA int )
0000528C: DELETE 01F36060 ( temp SSA int )
0000528E: CREATE 01F360F0 ( temp SSA int )
0000528E: ADD 01F360F0 ( temp SSA int ), 01F36000 ( temp SSA int ), 01F360C0 ( temp SSA int )
0000528E: DELETE 01F360C0 ( temp SSA int )
0000528E: DELETE 01F36000 ( temp SSA int )
00005290: ASSIGN 02102910 ( int ), 01F360F0 ( temp SSA int )
00005298: DELETE 01F360F0 ( temp SSA int )
0000529E: CREATE 01F36150 ( temp SSA int )
0000529E: ASSIGN 01F36150 ( temp SSA int ), 01F36120 ( const int )
000052A4: CREATE 01F361B0 ( temp SSA int )
000052A4: ASSIGN 01F361B0 ( temp SSA int ), 01F36180 ( const int )
000052AA: CREATE 01F36210 ( temp SSA int )
000052AA: ASSIGN 01F36210 ( temp SSA int ), 01F361E0 ( const int )
000052B0: CREATE 01F36240 ( temp SSA int )
000052B0: ASSIGN 01F36240 ( temp SSA int ), 02102910 ( int )
000052B8: ACTION 000C (4) 01F36240 ( temp SSA int ), 01F36210 ( temp SSA int ), 01F361B0 ( temp SSA int ), 01F36150 ( temp SSA int )
000052B8: DELETE 01F36240 ( temp SSA int )
000052B8: DELETE 01F36210 ( temp SSA int )
000052B8: DELETE 01F361B0 ( temp SSA int )
000052B8: DELETE 01F36150 ( temp SSA int )
000052BD: CREATE 01F36270 ( temp SSA int )
000052BD: ASSIGN 01F36270 ( temp SSA int ), 02102910 ( int )
000052C5: CREATE 01F362D0 ( temp SSA int )
000052C5: ASSIGN 01F362D0 ( temp SSA int ), 01F362A0 ( const int )
000052CB: CREATE 01F36300 ( temp SSA int )
000052CB: LT 01F36300 ( temp SSA int ), 01F36270 ( temp SSA int ), 01F362D0 ( temp SSA int )
000052CB: DELETE 01F362D0 ( temp SSA int )
000052CB: DELETE 01F36270 ( temp SSA int )
000052CD: TEST 01F36300 ( temp SSA int )
000052CD: DELETE 01F36300 ( temp SSA int )
000052CD: JZ 000052F7


And lastly, perhaps getting ahead of myself, the same segment after running it through my variable optimization pass:

00005275: CREATE 01F36000 ( temp SSA int )
00005275: ACTION 0010 (0) 01F36000 ( temp SSA int )
00005282: CREATE 01F36060 ( temp SSA int )
00005282: ACTION 00E8 (1) 01F36060 ( temp SSA int ), 02102C10 ( merged string )
00005287: CREATE 01F36090 ( temp SSA int )
00005287: ACTION 0010 (0) 01F36090 ( temp SSA int )
0000528C: CREATE 01F360C0 ( temp SSA int )
0000528C: SUB 01F360C0 ( temp SSA int ), 01F36060 ( temp SSA int ), 01F36090 ( temp SSA int )
0000528C: DELETE 01F36090 ( temp SSA int )
0000528C: DELETE 01F36060 ( temp SSA int )
0000528E: ADD 02102910 ( merged int ), 01F36000 ( temp SSA int ), 01F360C0 ( temp SSA int )
0000528E: DELETE 01F360C0 ( temp SSA int )
0000528E: DELETE 01F36000 ( temp SSA int )
000052B8: ACTION 000C (4) 02102910 ( merged int ), 01F361E0 ( merged const int ), 01F36180 ( merged const int ), 01F36120 ( merged const int )
000052CB: CREATE 01F36300 ( temp SSA int )
000052CB: LT 01F36300 ( temp SSA int ), 02102910 ( merged int ), 01F362A0 ( merged const int )
000052CD: TEST 01F36300 ( temp SSA int )
000052CD: DELETE 01F36300 ( temp SSA int )
000052CD: JZ 000052F7


For those keeping score, that's 17 instructions in the original bytecode, 43 in the raw intermediate code (26 that are create or destroy, 9 that are assigns to temporary variables), and 19 in the optimized intermediate code (10 that are create or destroy; if that still sounds like too many, note that all of those variables will be converted to registers in LLVM).

Monday, August 02, 2010

& NWScript

The attentive might have wondered why I bothered to spend a moderate amount of timewriting about a topic I'd already moved past, which is kind of uncharacteristic of me. As I said before, I had looked at LLVM for a couple days a couple weeks prior to the corresponding blog post, then moved on (I can't recall if there was anything in between LLVM and cache-oblivious algorithms).

Well, part of the reason I didn't spend too much time on LLVM was because while it's neat, I didn't have an immediate use for it. However, a few days before I wrote said post Skywing randomly came up to me and asked if I wanted to write a native code compiler for NWScript, the scripting language in NeverWinter Nights 1 and 2, for the client and server he's been writing. Suddenly I had an immediate and interesting use for LLVM.

NWScript (for more information see this) is a language based on C, and supports a subset of the features. It supports only a small number of data types: int, float, string, and a number of opaque types that are more or less handles to game structures accessed solely via APIs. It also supports user-defined structures, including the built-in type vector (consisting of 3 floats), though it does not support arrays, pointers, etc. All variables and functions are strongly typed, although some game objects - those referred to with handles, such as the "object" type - may not be fully described by their scripting type. NWScript has a special kind of callback pointer called an action (a term which, confusingly, has at least two additional meanings in NWScript), which is more or less a deferred function call that may be invoked in the future - specifically, by the engine - and consists of a function pointer and the set of arguments to pass to that function (a call to an action takes no parameters from the caller itself).

NWScript is compiled by the level editor into a bytecode that is interpreted by a virtual machine within the games. Like the Java and .NET VMs, the VM for NWScript is a stack system, where a strongly-typed stack is used for opcode and function parameters and return values. Parameters to assembly instructions, as with function calls, are pushed on the top of the stack, and instructions and function calls pop the parameters and, if there is one, push the result/return value onto the top of the stack. Data down the stack is copied to the top of the stack with load operations, and copied from the top of the stack to locations further down by store operations.

Unlike those VMs, however, NWScript uses a pure, integrated stack system, implementing global and local variables through the stack, as well. Global variables are accessed through instructions that load/store values at indices relative to the global variable pointer BP, which is an index into the stack. Normally, global variables are at the very bottom of the stack, pushed in a wrapper function called #globals before the script's main function is called; there are opcodes to alter BP, though this is not known to ever be used. Local variables are accessed by loads and stores relative to the top of the stack, just as with the x86 (ignoring the CPU registers). Unlike the x86, however, return addresses are not kept on the stack, but like Itanium are maintained in a separate, program-inaccessible stack.

Oh, and for those wondering, the Java and .NET VMs have separate mechanisms for global and local variables that do not use the stack. This is actually rather surprising - you would expect them to use the stack at least for local variables, as actual processor architectures do (when they run out of registers to assign).

The following show a couple random pieces of NWScript bytecode with some comments:
; Allocate int and object local variables on the stack
0000007F 02 03 RSADDI
00000081 02 06 RSADDO
; Push parameter 0
00000083 04 06 00000000 CONSTO 00000000
; Call game API function
00000089 05 00 0360 01 ACTION GetControlledCharacter(0360), 01
; Copy return value to the object local variable
0000008E 01 01 FFFFFFF8 0004 CPDOWNSP FFFFFFF8, 0004
; Pop the return value
00000096 1B 00 FFFFFFFC MOVSP FFFFFFFC

; Allocate float on stack
00000015 02 04 RSADDF
; Incredibly stupid way of setting the float to 3.0f
00000017 04 04 40400000 CONSTF 3.000000
0000001D 01 01 FFFFFFF8 0004 CPDOWNSP FFFFFFF8, 0004
00000025 1B 00 FFFFFFFC MOVSP FFFFFFFC
; Assign the current stack frame to BP
0000002B 2A 00 SAVEBP
; Call main()
0000002D 1E 00 00000010 JSR fn_0000003D
; Restore BP to what it was before (not that it was anything)
00000033 2B 00 RESTOREBP
; Clean up the global variables
00000035 1B 00 FFFFFFFC MOVSP FFFFFFFC
0000003B 20 00 RETN

; Push last two parameters to FloatToString
0000043C 04 03 00000009 CONSTI 00000009
00000442 04 03 00000012 CONSTI 00000012
; Divide 5.0f by 2.0f
00000448 04 04 40A00000 CONSTF 5.000000
0000044E 04 04 40000000 CONSTF 2.000000
00000454 17 21 DIVFF
; Return value of DIVFF is the first parameter to FloatToString
00000456 05 00 0003 03 ACTION FloatToString(0003), 03
; Return value is second parameter to SendMessageToPC. Push first parameter.
0000045B 04 06 00000000 CONSTO 00000000
00000461 05 00 0176 02 ACTION SendMessageToPC(0176), 02
Stack systems - especially this one, where everything is held on the stack - make for VMs that are very simple and easy to implement, and Merlin told me in the past that they're easy to compile to native code, as well. So it's not surprising that the developers used this architecture for NWScript.

You might notice that Skywing has started a series of his own on the project, today. I actually wrote this post several weeks ago, but was waiting until the project was done to post about it. But now that it looks like he's gonna cover it, I need to start posting or I'll end up posting after him despite starting before him.

Sunday, June 27, 2010

& LLVM

A few weeks ago - before I got into cache-oblivious algorithms - I briefly had a different topic du jour. In particular, I had just learned about Low-Level Virtual Machine, and spent a couple days researching that.

LLVM is a bit hard to explain, because the boundary around what it is is rather fuzzy. To sum it up in a noun phrase, I'd say that LLVM is a modular compilation system and virtual machine. I say "compilation system" because it doesn't really consist of an actual compiler, and there's a lot of it that is outside the definition of a compiler.

The core idea is that you have a program in some programming language which is compiled into a platform and language independent intermediate format. From there, the program is translated into some machine code (whatever type is used on the machine it's being run on) at a later time, either during execution (just-in-time compiling) or prior to execution (e.g. an installer converting the application to native code when the program is installed), and executed. In that sense there's some similarity to the .NET platform and Java platform, though it isn't totally analogous to those.

LLVM is a collection of modules that makes the various parts of the process possible. These components form a redundant superset of a full system, so you can choose which you want for a particular purpose and leave the rest.

Going chronologically through that process, the first module in LLVM is its assembler. LLVM does not directly parse and compile any particular programming language. When creating a working compiler, you must create a language parser that processes a program and performs any language-specific optimizations. LLVM takes as its input a program in LLVM assembly plus various metadata that could be useful later in the process, and assembles them into language and platform independent LLVM intermediate bytecode. A few of the open-source parsers already available for LLVM include C, C++, Objective-C, and many others; there are even parsers under development that take .NET and Java bytecodes as input.

The LLVM assembly language differs substantially from the Java and .NET bytecode languages, and bears some resemblance to RISC assembly languages such as MIPS and PPC. LLVM assembly consists of an infinite set of Single Static Assignment (SSA) registers; each register can be assigned only once, and a new register must be allocated for the result of every computation. However, LLVM also stores a significant amount of metadata, such as call graphs and other things at a higher level than a simple assembly language, in the bytecode (language-dependent metadata provided by the compiler is also stored for later use by language-dependent modules, e.g. if a particular language has a runtime environment that needs more information than just the native code). This combination of the assembly language design and rich metadata allows the optimizer and native code generator to act much more effectively, in a language-independent manner, than if they were working on a bare assembly language. Yet they are compact enough to not be significantly larger than the equivalent native code alone.

The next step in the process is global optimization. LLVM implements a substantial number of language-independent optimization algorithms, and compiler writers can use some or all of them as they like. Because of the metadata stored with the assembly language, LLVM is not limited to dealing simply with assembly, and the effectiveness of it's optimization algorithms resembles that of a standalone compiler (e.g. Visual C++). Even better, because optimization occurs after the entire program has been assembled, LLVM can do whole-program optimizations (known as link-time code generation in VC++ and others) that are outside the ability of simple compilers that only look at a function or a source module at a time.

After optimization comes native code generation (or, alternately, you could interpret the bytecode without producing native code). This step takes the assembly and metadata that has undergone language and platform independent optimization and creates executable machine code, usually after performing platform-specific optimizations, and the code is then executed. Native code generators are language-independent, interchangeable modules invoked by LLVM and, given a program in LLVM bytecode, native code can be generated for any platform that a native code generation module exists for (x86 and PPC are a couple that are already supported with open-source implementations).

Finally, LLVM provides a runtime system that allows for various runtime tasks to be performed. We'll get to the other tasks later, but one to mention here is that this runtime system allows language or platform specific runtime environments to interface with LLVM-generated native code, as well as interfacing with system or dynamic link libraries. Language-dependent metadata provided by the language compiler in the distant past is also available for use here.

So, that's the basic process. However, as I've been describing the logical process and not the details, this description is much more linear than reality. As was mentioned, LLVM provides a number of modules that may be optionally used, and some are redundant. As well, there's also flexibility in how the modules interact.

LLVM especially provides a great deal of flexibility in the timing of optimization and native code generation. While LLVM can be used like a normal compiler, taking in LLVM assembly and generating an executable with native code that can be directly executed on the target platform, it does not need to be. It's equally possible to store the LLVM bytecode in a platform-independent "executable" and optimize it and compile it to native code at a later point, either on execution or prior to execution. LLVM can even compile individual functions to native code the first time they are called, allowing some portions of the program to potentially never be compiled at all.

Finally, LLVM also supports profiling and dynamic recompilation of a program. The LLVM runtime is capable of profiling the native code of the program at runtime, determining where the program spends most of its time, what functions are executed most often, etc. based on actual usage. It can then recompile the program from bytecode, either between executions or during idle time, using this profile data to perform optimizations based on actual usage.

So, that's squishy. But why should you care? Well, a few reasons. Probably the most attractive is that you can make a full, optimizing compiler for a language that will generate native code for many platforms simply by writing a parser and LLVM assembly generator - thousands of lines of code compared to hundreds of thousands or millions (see here for one example of this). Alternately, if you're designing a processor for some reason (work, school, or hobby), you can write a native code generator and instantly support all the languages parsers already exist for. And then there are some less obvious uses, such as using the metadata generated by LLVM to perform complex analysis of source code for the purpose of searching for bugs, security holes, etc.

LLVM is a free open-source project that may be used in free or commercial projects, open-source or proprietary. Its largest benefactor is Apple, who uses it extensively. Other companies such as Adobe also use it in various ways. For more information, see this brief summary of the LLVM system, and the LLVM web page.

Wednesday, June 23, 2010

& Cache-Oblivious Algorithms (Updated)

Hey, does anybody remember the days when I actually wrote stuff on this blog? Those were good times.

Well, in case anybody actually remembers that far back, one of the things I'm known for is my topic du jour manner of self-education. I hear about some topic (or it comes up in some thought process), I research it for anywhere from a few days to a few months (however long it holds my interest), then I move on to some other topic. This week's topic du jour is cache-oblivious algorithms.

To explain what cache-oblivious algorithms are and why they're good, let's work through an example.

Suppose we've got a sorted array of 2^24 32-bit values, for a total size of 64 MB, and we need to determine if it contains a given value (if not, to find the nearest values). As we know that the list is sorted, binary search is the obvious choice, as it's known to be O(log N) complexity; note also that a sorted array is effectively an implicit binary search tree with items stored in-order, and the binary search is just a traversal of that tree. This complexity dictates that the search will require approximately log2(2^24) = 24 comparisons, each by definition involving a memory access (obviously, as the array is stored in memory).

Now consider a similar array containing 2^8 32-bit values (total size of 1 KB). According to the big O, a search through this array will take about 8 comparisons - 1/3 as many as the 2^24 array. Now, while these two numbers are accurate, they're highly misleading. By that measure, you'd expect it to take three times as long to perform the 2^24 search as the 2^8. It doesn't. In fact, the difference is well over an order of magnitude.

The reason for this discrepancy is the assumption that all memory accesses are equal. This is invalidated by the existence of processor (and other) caching, where cache hits are significantly faster than cache misses, as well as Non-Uniform Memory Architectures, where different memory banks have different access times for different processors. The 1 KB array can easily be held entirely in the processor's L1 cache, and in theory all accesses will be cache hits. The 64 MB array, on the other hand, can't even be held in L2 or L3 cache, so most memory accesses will be cache misses, and must go all the way to main memory.

Of course, main memory isn't that extreme of an example, as it isn't too much slower than processor cache. The real killer is when you have something (e.g. a database) that can't be held entirely in memory, and must be read from disk as needed (or worse, accessed over the internet at a speed that makes hard disks look fast). Hard drives are about a million times slower than RAM, meaning that each and every disk access is an excruciating performance hit, and the internet can be an order of magnitude worse.

Unsurprisingly, a massive amount of research effort over the last half a century has been in minimizing that amount that must be read from disk, especially in the class of cache-aware algorithms. Cache-aware algorithms are algorithms that are tuned (typically parametrized) for a specific system configuration (e.g. cache size) to achieve performance superior to algorithms that don't take such configuration into consideration.

One of the most common cache-aware algorithms, used in most file systems and database structures, is the B-tree (and family members), an upside-down (non-binary) search tree designed to minimize the number of disk accesses in searching data sets too large to fit entirely into memory. The B-tree is cache-aware because the block size can be adjusted to perform optimally on a given system configuration through either abstract math or actual benchmarks, and the optimal size for one configuration may perform poorly on another configuration.

Surprisingly, only in the last decade have people seriously investigated whether it is possible to create algorithms that make optimal use of a system configuration regardless of what exactly that configuration is, with no parametrization. This type of algorithm is called cache-oblivious algorithms.

Sometimes this is easy. A sequential scan of an array that does something on every element in order is cache-oblivious because it produces the provably minimum number of cache misses regardless of how the cache works. Divide and conquer algorithms that access each item in an array are also generally cache-oblivious and provably optimal because they ultimately divide enough to operate only on what's in a single cache line, regardless of what size the cache line is, before moving on to the next cache line (assuming, of course, that the size of each element is small in relation to the size of a cache line); in other words, they have a more or less linear scanning memory access pattern.

Binary search, however, is not cache-oblivious, as it's not a true divide and conquer algorithm in the sense that matters to us; specifically, it does not access all elements, and therefore does not get to take advantage of the predominant locality in the array. However, we can make a cache-oblivious implicit binary search tree by changing the ordering of items. To maximize performance, we want to lay out the nodes of the binary tree such that child nodes are as close as possible to their parents as often as possible, resulting in a minimal number of cache misses.

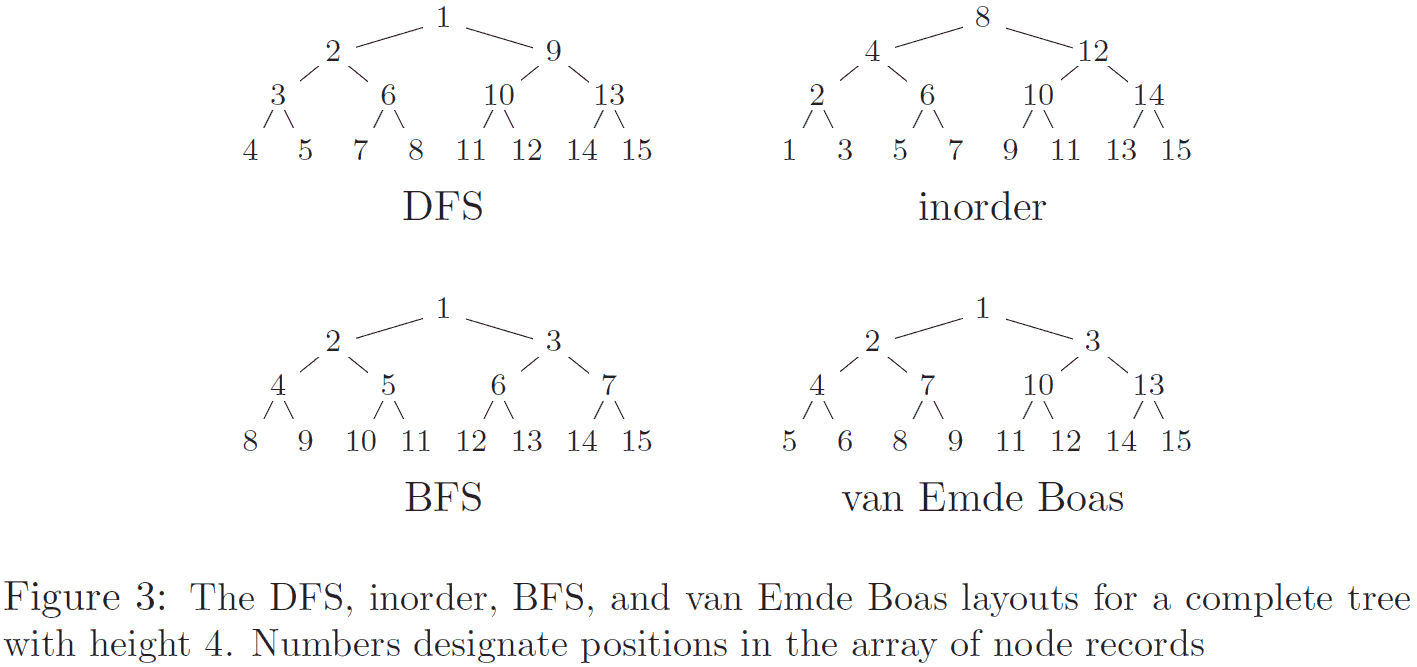
The key here is what's called the van Emde Boas layout (VEB) (you can tell I use HTTPS Everywhere because my Wikipedia links are all HTTPS). The basic idea is that the (triangular when drawn on paper) tree is divided recursively into (triangular) subtrees, with all nodes in each subtree being clustered together. This gives it a fractal structure with child and parent nodes being as close as possible to each other, maximizing cache locality during searches without needing to know the details of the cache system. A short tree in this form is shown below; below that is a comparison with trees in in-order, breadth-first (BFS), and depth-first search (DFS):


It's worth noting that cache-oblivious structures may or may not be as fast/faster than the simpler forms when the entire data set is in the same level of cache (whether you're talking about L1, RAM, etc.). One of the papers (the same one the images are from) examined the performance of static (non-changing) binary trees stored in in-order, BFS (an order that gives some cache locality while still being trivial to calculate child positions for), DFS, and VEB order, as well as two cache-aware search tree formats. In this experiment, the tree was stored in memory and cached in the processor cache - cache hits stay in the processor, cache misses go to main memory.

In the case of VEB, the complex fractal structure makes it nontrivial to calculate the position of a node's children in the array. As a result, when the entire data structure is in cache, calculation of child position takes longer than memory accesses, and VEB is about 40% slower than the standard in-order ordering. VEB begins to outperform in-order ordering once about half of the tree does not fit into cache; this calculation complexity problem can be overcome by storing child pointers with each node, but this is rather self-defeating, as this only multiplies the amount of data that has to be fit into the limited cache. In almost all cases, the cache-aware algorithms were superior to the others, but obviously require tuning to the particular cache, which is exactly what we're trying to avoid. BFS also performed admirably, always at least 15% faster than in-order ordering, and superior to VEB when more than ~1.5% of the data was able to fit into cache.

Another article compared a cache-oblivious binary heap based on VEB ordering with a standard binary heap using BFS ordering, in the context of a real-world internet page cache in actual use. Here, the heap is stored on (solid state) disk and cached in memory - cache hits go to memory while cache misses go to the disk. As in the previous benchmark, VEB performed 30% worse than the standard BFS when the entire tree could be stored in cache, but outperformed BFS when more than 0.2% of the tree was not stored in memory (I would guess this threshold is so low due to the many order of magnitude difference between memory and disk performance). At the other end, VEB peaked at 10x the speed of BFS when most of the tree was not cached. I imagine the reason this wasn't much higher was that in this real-world benchmark the priority queue was very small relative to the other data that is being accessed, and as such performance was dominated by other operations.

In the ~10 years researchers have been working on this, an array of cache-oblivious algorithms have been described, such as searching, sorting, linked lists, heaps, matrix multiplication and transposition, and various geometric algorithms such as 3D bounding volumes. The list of stuff I've seen so far (though not necessarily read through completely) is shown below, though I'm certain there are other things out there as well.

Cache-Efficient Layouts of Bounding Volume Hierarchies [and space partitioning]
Cache-Oblivious Algorithms (overview and survey)
Cache-Oblivious Algorithms and Data Structures (overview and survey)
Cache Oblivious Distribution Sweeping (sorting and various geometric algorithms)
Cache-Oblivious Dynamic Search Trees
Cache-Oblivious Priority Queue and Graph Algorithm Applications
Cache Oblivious Search Trees via Binary Trees of Small Height
You're Doing It Wrong (overview and heap algorithm applied to a real-life internet cache program)

Friday, April 30, 2010

& Domain-Specific Computing

So, I went to the public lecture at UCI today (the one I posted an event for on my Facebook page). These public lectures are by various guest speakers on a wide range of topics; each one is usually something of an overview of a particular field, often ones which the average computer science student has minimal or no exposure to in their classes. As with last time, there were free brownies and coffee/tea.

Note that this post is all from memory. I didn't take notes or anything, so there are likely to be omissions and vagueness compared to the actual lecture.

The topic this time was domain-specific computing. Essentially this refers to the use of some manner of special-purpose hardware to offload work from a general-purpose CPU, either eliminating the CPU entirely or allowing the use of a smaller, cheaper, and more efficient CPU. The ultimate purpose of this is to reduce overall cost and power consumption while increasing overall performance for a given task.

If this doesn't sound revolutionary, it's because it's not. Modular electronics have been around for as long as electronics in total. If you want a real-world example of something built this way, you can look at just about anything at all. Computers consist of many components (e.g. motherboard, video card), each composed of many further components (GPU, southbridge, northbridge, etc.), usually microchips.

The problem then is that it's hard to manufacture these chips. It's expensive, requires skill in engineering, and is largely done manually. Skilled electrical engineers must manually design a circuit, then a huge fabrication plant uses big and very expensive machines to manufacture the circuit, which is then available for use in various devices. Because of the expense and manufacturing requirements, most companies are not able to produce custom chips in this way.

As a result, very common specialized circuits are produced and sold off-the-shelf in large quantities, while less general circuits instead use code running on a general-purpose CPU. After chip design and fabrication, another electric engineer must then analyze everything a particular device must do, determine where it would be beneficial to use specialized off-the-shelf components (which may either be used directly or require some manner of mapping to make the data fit the exact component), then determine which CPU to use for everything else, and have the programmers write the code for it.

Done correctly, the resulting device is faster, cheaper to manufacture, and more efficient than simply using a fast CPU to do everything. One of the papers he cited examined different algorithms implemented on a general-purpose CPU, a general-purpose GPU, and a custom FPGA (chips that can be programmed without massive fabrication plants, but are less efficient than standard fabricated chips). For one algorithm (seemingly a highly parallel one), the GPU performed 93x as well as the CPU, and the FPGA 11x. While the GPU was 8x as fast as the FPGA in absolute terms (though presumably you could increase the size of the FPGA 8 times, to match the GPU's total performance), when you compare performance:power consumption, the GPU was 60x that of the CPU, and the FPGA was about 220x: about 3.5x the performance of the GPU (and I'd wager the FPGA cost less than either of them). In other algorithms, the difference was tens of thousands of times.

But it's still a whole lot of work. Consequently, this tends to be done for mass-produced electronic devices, while more specialized things are simply executed on a common computer, as it's cheaper to code a program than engineer an electrical device.

This guy (the one who gave the lecture) is working to develop analysis and automation tools to reduce the cost and difficulty of custom hardware development, to significantly increase the range of things that are viable to produce this way. Ideally, you'd be able to write a specification or algorithm (e.g. a C++ program that describes an entire device's function), then automation would analyze the system, performing these steps (essentially the same ones I summarized above):
  1. Break it down into major functional units
  2. Determine which units can use off-the-shelf components and what the optimal component is
  3. Locate algorithms that would substantially benefit from the production of new components and then design those components for manufacturing, either using FPGAs, circuit boards, or as actual fabricated chips
  4. Choose the optimal CPU and algorithm for the tasks remaining (that aren't worth implementing in hardware) and write the code. Remember that different tasks run better or worse on different CPU architectures, so this step must find the best CPU for the given algorithm or rewrite the algorithm in a way that runs better on a more preferable (e.g. cheaper) CPU. For example, CPUs that lack branch prediction are cheaper and more energy-efficient, but perform poorly on algorithms that use a great deal of branching; however, depending on the task to be performed, an alternate algorithm might be able to perform the task with less branching.
  5. Design an optimal bus architecture for all the different electronic to communicate
Of course, it's very likely that this ideal is fundamentally impossible - at least until artificial intelligence is able to perform as well as a skilled electrical engineer. However, he hopes to create tools that drastically reduce the amount of human time and cost needed for this process, and the talk was about recent research toward that goal. A few of the automation problems under research by different groups:
  • Identification of identical algorithm matches to existing circuits as well as partial matches that can work with some amount of data conversion
  • Profiling of different matching circuits to determine which performs optimally on a given problem
  • Determination of which algorithms would perform substantially better if implemented in custom hardware
  • Conversion of procedures (e.g. C++ programs) to electronic schematics for manufacturing
  • Profiling of different CPU architectures (e.g. x86 and ARM), models (e.g. i5 and i7), and variants (e.g. cache size, with or without optional subunits, etc.), to determine which is optimal for a given device, based on performance and cost
  • Profiling of different bus architectures (e.g. mesh and crossbar) and configurations (e.g. number and size of channels) to determine what is optimal for a device
  • Modularization for energy efficiency, to allow entire circuits to be shut off when they aren't in use (but others are)
I don't remember too much more detail than what I've already said. One last point is that this guy seemed to be a big fan of the multiband radio-frequency interconnect (RF-I) bus for the purpose of inter-component communication. This works essentially the same as the radio or broadcast TV, where bandwidth is split into separate channels, each with a different range of modulation frequencies. As this allows bandwidth to be arbitrarily allocated between many bus channels (and may even be configured in real time), this is very amenable to communication and power optimization.

Actually, it looks like the slides from the lecture are available online for you to look at, beyond what I've already written about it.

Friday, April 16, 2010

& MPQDraft and StarCraft 2

In the course of randomly wasting time today, I decided to go look at how MPQDraft is doing in terms of popularity, these days. I do that every so often, but it had been a few months since I last looked.

To my surprise, I noted a substantial spike in downloads: 50% more binary downloads and 100% more source downloads, beginning in February. It took me a second to realize the likely cause: SC2 going into beta mid-February. It's not clear to me whether people expect MPQDraft to work with SC2, or whether SC2 has inspired a more general revival in modding.

In any case - MPQDraft does not work with the SC2 beta. There are two reasons for this.

Part of why MPQDraft is so elegant is that it works in a game- and version-independent manner. This is possible because MPQDraft intercepts function calls between the games and the Storm DLL, the latter which contains the functions to access MPQs. This only works if Storm is dynamically linked to the game, in its own DLL. The SC2 beta statically links to Storm; the MPQ functions, as well as others, are incorporated directly into the game executable.

This means the current simple, elegant MPQDraft method will not work, period. The only way to deal with this problem, and to make MPQDraft work when the game statically links to Storm, is to directly locate the function addresses in the game, and include those addresses themselves in the MPQDraft DLL.

The problem with this is that it's game- and version-dependent. Every time a new patch comes out you'll have to wait until I or somebody else updates the function addresses before you can use MPQDraft on the new version. And this obviously requires somebody taking the time to manually locate the functions in every new version, from scratch.

So, that's in the "pain in the ass" class of problems. It also remains to be seen whether Blizzard intends to ship SC2 linked in this way, or if it will dynamically link to Storm in the release version.

The bigger problem is the fact that SC2 is online most of the time, including when you're playing single player (unless you specifically tell it to run in offline mode). Depending on how aggressively Blizzard performs its anti-cheating scans (which they've been doing since SC1), it's plausible that MPQDraft could be detected as a cheat, in which case you'd probably get your account banned.

That's the current state of MPQDraft and SC2.

Saturday, February 06, 2010

Let's Do Some Math!

There are a couple common equations of importance for what I'm working on at the moment. Both of them involve the idea of a set of items, where each item has a probability of being chosen (and more than one may be chosen in some cases). It's trivial to go item by item, draw a random number, and see if that item is chosen, but this is obviously inefficient. I wanted equations that would allow me to stick in a single random number and it will tell me the first relative item to be chosen, with a fixed number of operations.

The first equation is based on each item in the set having an equal probability of being chosen (note that more than one may be chosen, or none may be chosen):
probability(item) = perItemProbability

The general form of this decision is (rnd <= perItemProbability), where rnd is between 0 and 1 (as is the case with all instances of rnd in this post). Trivial. The equation we want to derive, however, not quite as much.

While it's tempting to think that the probability of any of n items being chosen is (perItemProbability * n), it's not. This isn't a linear function. Rather, you have to derive it from the probability that NONE of those items will be chosen, which is exponential.

(1 - perItemProbability)^n : probability none of n items will be chosen
1 - (1 - perItemProbability)^n : probability that at least one of n items will be chosen
rnd = 1 - (1 - perItemProbability)^n : switch out probability for a random number
1 - rnd = (1 - perItemProbability)^n : arithmetic rearrangement
log(1 - rnd) = log(1 - perItemProbability) * n : take the log of both sides
log(1 - rnd) / log(1 - perItemProbability) = n : arithmetic rearrangement

This gives us what we want: the index of the first chosen item. Of course you have to watch for values that result in taking log(0). You also have to notice that the range of the result is [0, infinity]; this is correct, but if the value is greater than the upper bound of your set of items, you have to recognize that no item was chosen.

Next up is the case where the probability of each item follows a geometric series:
probability(n + 1) = probability(n) * (1/divisor)
probability(0) = p0
sum of probabilities = 1

With this series there's no misleading simple solution, so we're forced to go straight to a more complex one. We know the sum of all the probabilities is 1, but we don't know what value of p0 to use to produce that sum. We can trivially calculate this using the geometric series equation:
1 = p0 * (1 - (1/divisor)^n) / (1 - (1/divisor)) : geometric series equation
p0 = (1 - (1/divisor)) / (1 - (1/divisor)^n) : arithmetic rearrangement

Okay, that's the easy part. Now the equation itself. Here again we'll solve for n:
rnd = p0 * (1 - (1/divisor)^n) / (1 - (1/divisor)) : substitute rnd for sum of probability
rnd / p0 * (1 - (1/divisor)) = 1 - (1/divisor)^n : arithmetic rearrangement
1 - (rnd / p0) * (1 - (1/divisor)) = (1/divisor)^n : arithmetic rearrangement
log(1 - (rnd / p0) * (1 - (1/divisor))) = log(1/divisor) * n : log of both sides
n = log(1 - (rnd / p0) * (1 - (1/divisor))) / log(1/divisor) : arithmetic rearrangement

And thus the solution: a long, ugly equation to calculate something simple. Again, you have to watch for values that result in errors: divisor must be greater than 1; but that's pretty obvious: a geometric series will only sum to a finite number if (1/divisor) is less than 1. You also have to note that when rnd = 1, n = the number of items in the set, which will be out of bounds.

Isn't math fun?

Tuesday, January 12, 2010

Computer Book Library

This post lists some of the computer books I have on my shelf, between text books and books I bought outside of school. This list is meant to provide readers with books they might be interested in reading, and so is limited to the books most likely to be of interest to others. While I list the versions that I have, myself, the links to the books on Amazon are to the most recent edition at the time of writing about them.

This post is likely to be updated from time to time in the future.

3D Game Engine Design, 2nd ed
David Eberly, Morgan Kaufman, 2006
Covers development of a 3D game engine that includes graphics, physics, and a few lesser topics (though the focus on the book is definitely graphics). Covers both the theory behind concepts and actual implementation of a complete working engine; this latter point makes it vastly superior to more typical graphics books, which usually cover the theory but not a complete implementation.

Artificial Intelligence, 5th ed
George Lugar, Pearson Education, 2004
Computer science textbook I used in the senior-level course.

C++ Programming: Program Design Including Data Structures,
D.S. Malik, Couse Technology, 2002
First year (for me) college textbook

Code Complete
Steve McConnell, Microsoft Press, 1993
Handbook of coding best practices for minimizing bugs and improving maintainability.

Developing Windows NT Device Drivers
Edward Dekker and Joseph Newcomer, Addison Wesley, 1999
A rather dated guide to programming Windows NT (4.0) device drivers.

Developing Your Own 32-Bit Operating System
Richard Burgess, SAMS Publishing, 1995
Prior to the Linux phenomenon, this was pretty much the only book that showed you how to create a full, real, working operating system for a modern computer (at the time, anyway). Throughout the book the author codes the example MMURTL (Message-based MUltitasking Real-Time kerneL), a (some redundancy, here) 32-bit message-passing, preemptive-multitasking operating system that runs on x86 computers, in 32-bit assembly + C, and several sample programs (including the command-line interpreter and debugger) in C.

Fundamentals of Computer Graphics, 2nd ed
Peter Shirley et al., A K Peters, 2005
A fourth-year (for me) college textbook. Like most books of its kind, it teaches you the theory behind graphics (and, if you're lucky, gives you pseudocode for some concepts), but leaves you on your own to figure out how to create a working graphics engine (if you have the need to do so).

Fundamentals of Database Systems, 5th ed
Ramez Elmasri and Shamkant Navathe, Pearson Education, 2007
A fourth-year (for me) college text book on databases. Covers from the basics to the advanced, as well as SQL programming, both in theory and practice.


Game Architecture and Design

Andrew Rollings and Dave Morris, Coriolis Group, 1999
A guide to the complete development process for a commercial game. The first section covers developing a game idea and balancing gameplay, the second section covers project and team management, and the third section covers development from architectural design (the thing code is based on) to production and postmortem analysis. The vast majority of the book is at a higher level, summarizing the entire game development process and the lessons learned by the author from his experience in commercial game development, though the author does create a (simple) working game in the process (several other game ideas are discussed in various chapters, but not developed into the full games).

Game Coding Complete, 3rd ed
Mike McShaffry et a., Charles River Media, 2009
A guide to the game development process and development of game systems. While the scope of material in this book is much the same as other game programming books (e.g. Tricks of the Windows Game Programming Gurus), this book distinguishes itself on quality and scalability. All game programming books invariably contain a guide to the various APIs your game will need to use (e.g. DirectX) and a survey of game technology (e.g. 3D graphics, AI, and networking). However, most books teach you from the perspective of a hobbyist getting into game programming, teaching you easy things that work okay for small games, but lack the power and scalability to deal with a large commercial game (and omit things that aren't necessary for small games).

This book dedicates itself to filling in those gaps, addressing frequently-omitted topics such as the build process, memory management and resource caching, event management, scripting support (the engine the author creates throughout the book is actually a data-driven engine based on Lua scripting), debugging, parallel programming, etc. Of course, it also contains the mandatory survey of game-related technologies, but I haven't looked at those parts and don't expect too much, as most of them are best left to their own books (graphics, physics, networks, AI, etc.), given the overwhelming broadness of those fields.

Programming Applications for Windows, 4th ed
Jeffrey Richter, Microsoft Press, 1999
Perhaps better described by its older name, Advanced Windows, this is the gold standard in "advanced" Windows API programming - things such as multithreading, advanced memory management, DLLs (including DLL injection and function hooking), exception-handling, and advanced window messaging.

Programming Windows, 5th ed
Charles Petzold, Microsoft Press, 1998
The first book to read on Windows API programming. Covers a broad range of topics from basic windows and controls to more advanced topics such as (basic) graphics, printing, multithreading, network communication, etc.

Programming Windows with MFC, 2nd ed
Jeff Prosise, Microsoft Press, 1999
The definitive guide to the Microsoft Foundation Class library, a C++ framework that wraps the Windows API. Analogous to Programming Windows, this was the book to read if you needed to learn MFC, though as MFC is easier to program than the Windows API, this book covers topics beyond those in Programming Windows. MFC is essentially obsolete now that .NET has become so common, though I'm told some people still have to deal with it in older software at their jobs.

Tricks of the Windows Game Programming Gurus
André LaMothe, SAMS Publishing, 1999
The Game Programming Gurus has been pretty well respected throughout its life. This was the 2D Windows game incarnation of the series (also see the companion Tricks of the 3D Game Programming Gurus); it covered basic Windows programming, the various DirectX systems, and then a survey of the various fields in game programming (like those mentioned a ways back). As stated above, this (and presumably the 3D version, which I haven't seen) is more of an introduction to game programming than a reference that would be useful at a real game programming job.

Visual C# 2005 How to Program, 2nd ed
Paul Deitel, Pearson Education, 2005
Lower-division college textbook on C# programming (at my school C and C++ were first-year courses, C#/Java/etc. were second-year).

Lastly, a couple books on the list of things to buy:

Game Engine Architecture
Jason Gregory, A K Peters, 2009

Real-Time Rendering, 3rd ed
Tomas Akenine-Moller, Eric Haines, and Naty Hoffman, A K Peters, 2008

Sunday, January 10, 2010

Bibliography - Programming

This post is a partial directory of the various programming and reverse-engineering I've done over the last 12 years, especially those that produced some manner of result (program, specification, or processed data). This list may omit projects that are too old, too obscure, too uninteresting, or that I just don't remember off the top of my head; it also omits most projects that were done as assignments or term projects in school. With a handful of exceptions, all of these are entirely my own work. With the exception of the few most significant projects being moved to the top, the list is in alphabetical order.

This list may undergo updates in the future.

(CHK) Starcraft Map File Format [reverse-engineering]
Reverse-engineering of most of the Starcraft map file format. This was my first modding community project, and it was for this that I was invited to join Campaign Creations in 1998. This consisted of repeated edits of a map in the Starcraft map editor (StarEdit) and then observing the changes in the map file it generates. Perhaps one of the most impressive parts of this accomplishment was that the vast majority of this was done using nothing more than the DOS edit.com utility and Windows calculator; no true hex editor, no disassembler or debugger (at that time I wasn't even familiar with reverse-engineering), etc.

It looks like this spec has become difficult to come by these days. Campaign Creations appears to no longer have it (I'll have to get that fixed) and only a few modified and/or butchered copies of it found on Google, some lacking credits for who wrote it. So, here's the version I still have on my computer.

MoPaQ 2000 [programming]
This (a.k.a. MPQ2K) was the project that really put the name Quantam on the Blizzard game modding map: the first stable, full-featured MPQ editor. Prior to this there was already a full-featured MPQ editor (I think the name was MPQEdit), however the extreme instability and bugginess meant that it was widely considered worse than nothing, and rarely used.

MPQ2K was a command-line user interface for the Lelik MPQ API, a library that hijacked the Starcraft Campaign Editor (StarEdit) and called the MPQ-writing functions it contained (as Starcraft maps are packaged into MPQ archives), without ever knowing the details of the MPQ format, itself (it's worth noting that this is where I learned about breaking and entering into processes and hooking functions). At the same time as the library, Lelik released a sample editor (I believe the name was MPQ Archiver) that the MPQ2K interface design used as a starting point; it was very clumsy and minimalistic, however, and lacked the major features that would make MPQ2K popular, such as scripting. MPQ2K remained the MPQ editor for several years, until cumulative speed improvements finally allowed WinMPQ, a graphical MPQ editor, to seize the title of most popular MPQ editor.

Understanding the significance of a practical MPQ editor requires some knowledge of the context. Prior to the use of MPQs, the only option to modify Starcraft game data, apart from what could be done in the map editor alone, was StarDraft, the predecessor to MPQDraft. StarDraft allowed in-memory patching of most Starcraft data files, allowing much more than was possible with the map editor alone (e.g. modification of sound effects, graphics, gameplay data such as unit statistics, etc.). While this was a hugely important development that essentially founded the Starcraft modding community (apart from custom maps), StarDraft suffered from several severe shortcomings that drastically limited its practicality: it was version-specific (meaning that every time a Starcraft patch was released StarDraft had to be manually updated by the coder before it could work with the new version), it could not replace music and certain other files, and, perhaps most significantly, it tended to actually slow down the game, degrading gameplay noticeably.

Thus, StarDraft was the first revolution in Starcraft modding, and use of MPQ files was the second. The replacement of StarDraft with custom MPQs as the basis for community mods solved many of these problems that plagued StarDraft. Music files could now be patched (although a handful of relatively minor files remained unpatchable until the coming of MPQDraft); as well, as MPQs were used natively by Starcraft and other Blizzard games, rather than requiring hacking into the game via StarDraft, this approach meant no gameplay degradation; it also meant this method could be applied to other Blizzard games that used MPQs, not merely Starcraft. This made StarDraft obsolete overnight.

MoPaQ File Format [reverse-engineering]
The complete reverse-engineering of the MPQ archive format and publishing of what remains the authoritative modder's specification the format. Most of this was performed during development of MoPaQ 2000 2.0. While Lelik reverse-engineered StarEdit sufficiently to allow LMPQAPI to call functions in the Blizzard MPQ API in StarEdit, he never actually looked at the MPQ format itself. Thus the work fell to me to provide functions that didn't exist in StarEdit, by writing code that edited the MPQs directly (code which was then integrated into LMPQAPI 2.0). This was also where I first learned how to reverse-engineer a program via disassembly and debugging. While I gave out a lot of information about the format to a number of people on forums and other media, I didn't actually release a full spec document until some time later (the official version of the spec is here, though as it's a wiki it's been known to be vandalized from time to time).

MPQDraft [reverse-engineering, programming]
The third revolution in Blizzard game modding, MPQDraft perfected the MPQ file technique. Like StarDraft, MPQDraft consisted of a loader that actively invaded the game being patched by a mod; however, MPQDraft suffered from none of the problems of StarDraft: it was version (and game) independent, it finally solved the problem of unpatchable files once and of all, and did not produce any gameplay degradation.

Like StarDraft, MPQDraft allowed the creation of "self-executing MPQs", which allow authors of mods to conveniently distribute large, complex mods in single executable files. However, MPQDraft added support for a plugin system, which allowed developers to add on new functionality to mods, while still making use of the basic functionality of MPQDraft. A couple examples of the most noteworthy plugins developed for MPQDraft are MemGraft (now obsolete), which allowed modification of data stored in the Starcraft executable itself (as opposed to in the Starcraft data files), and ThunderGraft (described below).

MPQDraft is now open-source, on SourceForge. Surprisingly, it still gets more than 600 downloads each month (this is only counting downloads through the SourceForge page; mirrors such as the one on Campaign Creations would not be counted), despite the fact that the most recent game it works on, Warcraft III, is about 8 years old, now.

ThunderGraft [reverse-engineering, programming]
The third of my major modding programs, ThunderGraft adding the ability to play modern audio compression formats (e.g. MP3 and Ogg Vorbis) to older Blizzard games, especially Starcraft. Prior to Warcraft III, Blizzard games used either raw PCM (Diablo) or compressed ADPCM (Starcraft, Diablo II, and Warcraft II) audio formats to store music and sound effects; both formats were undesirable for mods because they were either very bulky (in the case of PCM) or resulted in noticeable loss of audio quality with sub-optimal file sizes (ADPCM). ThunderGraft replaced the entire music streaming system of the games with its own, using the FMod Ex audio library to perform audio decoding of any of the multitude of compression formats the library supports. To my knowledge, it is, six years later, still the only modding tool to attempt such a feat. I finally got around to cleaning up and releasing ThunderGraft as open source a couple months ago on SourceForge, though given that the most recent game it supports, Diablo II, is about 10 years old, and the fact that broadband has made small mod sizes less critical than it was 10 years ago, it sees little use today (only about 30 downloads through SourceForge per month).

Allocation Benchmark [reverse-engineering, programming]
A project to examine the relative performance of several memory allocators - the Windows heap, Windows low-fragmentation heap, Hoard allocator, and the Blizzard Storm allocator (SMem, a custom buddy allocator). Allocation, free, and resize operations were logged from an actual game of Warcraft III via function hooking, then fed in order to each allocator while the duration of each operation is measured, and the results compared. Covered some in various posts.

AUS Decode [reverse-engineering, programming]
This project consisted of reverse-engineering the archive (AIF) and digital audio (AUS) file formats in the Mega Man Anniversary Collection to create a decoder that could extract the music directly from the game. Both AIF and AUS file formats were previously unexamined and undocumented, although the audio compression algorithm turned out to be the documented Sony ADPCM variant VAG. Reverse-engineering of both formats was accomplished with nothing more than a hex editor (no disassembler or debugger). I talked a tiny bit about this, but never said much about the technical side of it or released the code.

(BIN) Diablo II Binary Data Format [reverse-engineering]
Reverse-engineering of a number of major Diablo II binary data formats, e.g. armor.bin, itemtypes.bin monstats.bin, treasureclassex.bin, etc. These files are compiled binary versions of the SLYK spreadsheet files containing game global data. This was originally done with the intent of making a data editor tentatively called HellForge, but I never got around to that. I don't believe I ever released the specs of the BIN files; if I did, it would have been on Phrozen Keep.

DxWnd [reverse-engineering, programming]
DxWnd allows full-screen DirectDraw games that do not support windowed-mode DirectDraw to run in a window. I can't remember whether the initial idea was mine or Skywing's, but I did the initial research and reverse-engineering for the program and came up with the basic method. Skywing then wrote the code and debugged the cases that required modifications to my basic method (e.g. programs that combine Windows GDI and DirectDraw for graphics, such as the Diablo/Starcraft/Warcraft 2 Battle.net interface). I later added code to support window resizing via Direct3D, rather than the standard drawing method using GDI, though I can't remember if that code ever got released.

E Terra [programming]
A real-time strategy game based on ecology and evolution. Because this game focuses on nature and the organic, rather than humanity and society, the gameplay is substantially different than any existing RTS I've heard of, though it's bears some resemblance to Populous. E.g. there are no unit classes - unit "classes" are created by the player through gameplay/evolution; units are not built/trained - they are born automatically; etc. Current status: awaiting the motivation to work on it more.

Engram [design]
The name a Portmanteau contraction of "English program", a programming language based on a subset of natural English. This was something I started working on early in my compilers class, when I heard we were each going to be writing a compiler as a term project. Work on it came to an abrupt end when I learned that we didn't get to choose the language for our compilers. Other than what I communicated to a friend in IRC and IM, I never really wrote down a specification or anything.

LibQ [programming]
A small, minimalistic cross-platform library (designed for at least Windows and POSIX support) of highly platform-dependent features, such as multithreading (more specifically, synchronization, inter-thread/process communication, and atomic operations and structures), endian-conversion, and high-performance file I/O. Talked about extensively on this blog, though that was before I started using tags or anything to make the posts easy to find.

NWNScript Compiler [programming]
A compiler capable of compiling NWScript, the world scripting language used in NeverWinter Nights, NWN2, and Dragon Age, to native machine code for use in Skywing's NWN2 standalone server. This is the first attempt at such a thing that I'm familiar with; both the original games and Skywing's standalone server previously implement interpreters to execute the scripts.

In addition to the analyzer, which parses the NWScript bytecode files and generates intermediate representation code, two backend code generators were created to produce native code by proxy. Skywing's backend generates .NET bytecode, which uses the .NET just-in-time compiler to generate partially optimized native code; my backend generates Low-Level Virtual Machine code, which uses the LLVM optimizer and JIT compiler to produce optimized native code.

Q1 [design, programming]
A fairly simple and elegant RISC processor design and emulator. The Q1 began as an idea for a term project in computer architecture class to create a simple CPU and emulator; like Engram, the Q1 was conceived and work began prior to learning that we couldn't design the instruction set (the whole purpose of the Q1). However, I stuck with this one long enough to finish the basic instruction set architecture and create an emulator and sample programs (though not an assembler, which made it a huge pain to program). A number of the design decisions were discussed on the blog.

Ray Tracer [programming]
As with just about everybody who has ever taken a graphics course, I had to make a simple ray tracer. As this was only one assignment (and not a term project), the emphasis was kind of on the simple (there was no requirement for support of meshes, reflection/refraction, etc. However, I really ended up getting into this one, and added a substantial amount of additional features beyond those required in the assignment. Thanks to all my additions, it easily grabbed the top spot in the class.

While I intended to, I never got around to writing much about the ray tracer and the various features I chose to implement (and why), though the project page on the school wiki summarizes the features and shows them off with various screen shots.

recMPQ [reverse-engineering, programming]
recMPQ was a simple program to test some revere-engineering work on the MPQ format. The World of Warcraft Burning Crusade expansion added several new MPQ format features related to support for large archives (greater than 4 gigabytes). However, at the time no actual archives used these features. Consequently, I was forced to rely on pure disassembly, without being able to look at properly-formed archives or even watch the game load an archive using these features. recMPQ was a program to make a large MPQ archive based on my disassembly findings, which I could then replace a BC archive with to observe whether the game was able to successfully load the archive (indicating I had properly used the new features). This information was ultimately added to my MoPaQ format specification.

TextBreaker [programming]
A system to identify the language of a block of text using artificial neural networks. This was my term project (and accompanying term paper) in artificial intelligence class, which integrated AI, my interest in linguistics, and my interest in biology all into one. Unfortunately, identifying languages isn't as easy as it sounds, and the project ended up being more educational - in the sense of revealing difficulties and what does and doesn't work - than remarkably successful at actually identifying text. Nevertheless, it did manage to impress the (undergraduate) class, the teacher (specializing in AI), and my grandpa (a professional linguist), and my teacher and grandpa both suggested that I continue work on it and submit my results to AI and linguistics journals.

I never got around to cleaning up the source to release it (I did the whole term project in a week and a half, which made for very hackish code), but I did post the accompanying Orthographic Language Identification Using Artificial Neural Networks paper back when I turned it in.

StormDump [reverse-engineering, programming]
A memory tracker and browser used to examine the memory use of Blizzard games. Unlike the benchmarking project mentioned above, which merely logged calls to the allocation functions, this project consisted of reverse-engineering of the memory allocation system itself, and the associated data structures. It logged each memory allocation made, and tracked how many allocations were made of given sizes and types, both at a particular time and in total, and allowed you to dump all memory allocated at a particular time via hotkeys. All of this was done by directly traversing the memory structures for the allocation system. I don't believe I ever gave this or the source out to anyone.

Watcher [programming]
A simple program that logs all calls to API functions in various libraries that you specify using an configuration file. Version 1 of this hooked only functions specified in specified DLLs via INI files; some functions, such as the MPQ APIs, had hard-coded parameter-logging functions. Version 2 was capable of hooking all functions in all libraries and was intended to be scriptable to allow function-specific parameter logging for logged functions, though scriptability was never actually implemented.

ZIC2RAW [reverse-engineering, programming]
A project/program to extract the digital music files from the 3DO version of Mega Race. The format actually ended up being quite trivial to reverse-engineer, though the files turned out to not be entirely self-contained - part of the music data was embedded in the game executable itself, and not stored in the separate music files. Apart from a tool to work with 3DO discs, all of the reverse-engineering for this was done with a hex editor.

Sunday, January 03, 2010

Random Fact of the Day

In .NET, String.GetHashCode computes the hash code every time the function is called. This is slightly surprising given that Strings are immutable, and thus could easily compute the hash code on construct or on the first call to GetHashCode (although both of those options do have associated overhead).

Someone I know believes that Java is the same way.

Monday, December 28, 2009

& Modern Things Part 3

So yeah, the Xbox 360 is pretty uninteresting, apart from the memory limitation. Fortunately, the third and final thing you can program with XNA is rather interesting: the Zune. The Zune is Microsoft's answer to the iPod: a portable music player. However, the Zune is also capable of running third-party programs through XNA. This makes it rather interesting, as it gives you the best taste of what it was like to program a console in the past (back before console CPUs were in the GHz and memory was in the hundreds of megs), as it has some of the same programming considerations (or at least moreso than the 360 or PC).

There are a few different models of Zune with different capabilities, which can be separated into what I'll call the 'Zune' (the first several models, which are pretty much identical for our purposes), and the recent Zune HD.


The Zune series is shown above. Members of the series vary in exact design, but all have a few common features. All models have a low-power ARM CPU, 64 megs of RAM, and has the ability to do basic bitmap graphics. They contain a 240x320 LCD screen in 3:4 aspect ratio (the screen size varies from 1.8 to 3.2 inches, diagonal), running at 30 FPS (some high-end models also support 60 FPS). For input, each has a circular pad as well as one button to each side of the pad.

These features give the Zune a unique set of programming considerations. Obviously, the CPU is drastically less powerful than on the PC or Xbox 360. Games have a quota of 16 megs of RAM usage, in which both code and data must fit (although as this is only 1/4 of the total RAM of the Zune, garbage collection overhead is much less of a problem, and you should be able to use all 16 megs without seeing too much garbage collection slowdown). Graphics are limited to 2D sprite-based operations, and screen space is very limited (the Zune actually has a quite impressive display resolution for its screen size, but it's still tiny). Of course, the fact that this is a portable system means that battery life is also an issue. But perhaps the most tricky issue is the input system.

The Zune is designed to be used standing up, as shown in the above picture. In this orientation, the screen is taller than it is wide. Control can use both thumbs, with one thumb on one button, and the other thumb shared between the circular pad and the second button. However, as games typically are designed around a screen that is wider than it is tall, this configuration comes off as somewhat unnatural, though some games are more appropriate for this than others (e.g. a top-down shooter would have no problems, here).

Alternately, the Zune may be turned on its side, yielding the standard 4:3 aspect ratio used on everything prior to high-definition televisions and wide-screen monitors. The chief problem with this configuration, then, becomes control. Due to the button configuration of the Zune, this configuration allows only one thumb for input, shared between the circular pad and the two buttons. This has the effect of drastically reducing the potential complexity of gameplay input, as it's far more cumbersome to switch between buttons than to simply have a second thumb take care of one of them.


The Zune HD is shown above. You could really call this the Zune 2 (or, if you're Nintendo, the Super Zune), as it's almost entirely different from the previously mentioned Zune series. It's powered by an nVidia Tegra (2600), a system on a chip which both acts as an (ARM) CPU and a GPU capable of 3D graphics (although thus far XNA does not support 3D on the Zune HD). As far as I know, the amount of memory on the HD has not been published, though it's safe to say it has at least 64 megs RAM. While the screen is only 3.3 inches (about the same as the higher-end Zunes), the screen is now 480x272 (when laid sideways) in the HDTV 16:9 aspect ratio.

Perhaps most significant, however, and the reason the Zune is much more interesting than the PC and Xbox 360, is the change in input system. As can be seen in the image, the Zune HD has no buttons or other controls. Instead, the HD features two new input methods: a multi-touch display and an accelerometer.

For those not familiar with it, multi-touch displays are a type of touch-screen, which take as input a point on the screen and the pressure exerted on the screen at that point. Multi-touch takes this to the next level by allowing multiple points of contact, including tracking of movement of each point. This allows for very flexible and powerful input, permitting such interfaces as "point and click" via pressing the screen at a point, dragging and dropping, and things such as gestures. This even allows interfaces such as the one seen in Minority Report (and other sci-fi-ish depictions), where multiple points of contact with the touch screen can be used to grab and move, rotate, or resize items on screen (this type of interface exists in the Microsoft Surface and other multi-touch devices; also, be sure to check out the Dungeons and Dragons on Surface demonstration).

You might not be able to guess what an accelerometer is, based only on the name: obviously it measures acceleration, but unless you're into physics, you probably wouldn't make the connection with gravity. Technically, holding an object in air (as opposed to letting it free-fall) requires an upward force to be applied to the object, and a force produces acceleration. An accelerometer measures this acceleration against the force of gravity; in other words, an accelerometer measures which direction is up, based on the orientation of the device. Of course, it also detects other types of acceleration, such as movement in space, as well. Between the possibilities, this allows a number of interesting (and impossible, with traditional input methods) input systems, such a basing the in-game camera on position and/or orientation of the Zune, actions triggered by bumping or shaking, etc.

Microsoft makes the multi-touch screen and accelerometer available in XNA through the XNA Zune Extensions addon. Once you've downloaded that, search the help for Zune HD Input Overview for general information about support. After that, zunezune.org has posted a helpful simple "game" that demonstrates multi-touch and accelerometer: the code is available here, and a video of the program in action is below. Finally, Platformer: Adding Touch Support (also in Extensions help) is a tutorial that shows you how to add multi-touch and accelerometer support to the platformer starter kit.